Most document fraud detection tools report a risk tier, a handful of "signals," or a pass/fail flag. Few explain what they measured. Fewer still can point to the exact spot in a document that triggered the flag.
ThumbPrint©, MoneyThumb's patented fraud detection engine, was built to do both. It runs two independent models on every document, combines them into a single score, and attaches the reasons behind that score. The method is described in U.S. Publication No. 2023/0359815, "Detection of Altered Documents," filed by inventors Ralph Mayer and Erik Giles of MoneyThumb LLC.
This post covers how the patented method works, why the data behind it matters as much as the method itself, and what it means for the developers and product teams building lending workflows on top of it.
The problem the patent solves
The patent's background section cites a number every lender should know. Across the financial sector, up to 1% of statements submitted to support a loan or credit application have been altered. In the worst cases, the entire document is fabricated. Modern PDF editors make convincing edits easy for anyone.
That 1% is an average across all of SMB financing. In higher-risk segments like MCA and subprime SMB lending, the rate climbs. A few reasons drive this:
- Fraudsters often assume fast-decision underwriting is simple and won't catch small edits, so the perceived odds of success are better.
- Speed-to-fund is a selling point in this market, and fraudsters read it as less scrutiny per file.
- Merchants with thin files, recent declines, or existing advances have more motive to inflate balances or hide NSFs.
- Broker and ISO submission channels put more hands between the merchant and the funder, which creates more points where a document can be touched.
Across the statements MoneyThumb processed in this segment over the last year, 3.91% were flagged for likely fraud. That is up roughly 15% from the year before and nearly four times the patent's cross-industry baseline.
Older fraud tools rely on file metadata: last-modified timestamps, edit flags, incremental save history. That works until someone re-saves the file, prints it to a new PDF, or runs it through a metadata scrubber. The evidence disappears and the altered document looks clean. ThumbPrint analyzes the content and structure of the document itself, so the signal survives those tactics.
Model one: intra-document consistency
The first model checks a document against itself. It examines how the PDF is built at the object level, including the specific PDF operators used to position text and data on the page, and looks for internal patterns that break.
Per the patent claims, artifacts this model can identify include:
- A character in a column of numbers (often a decimal point or the leftmost digit) sitting at a different horizontal position than the rest of the column
- Two dates in the same document using different formats
- A contiguous string of text that changes font type or size partway through, or uses a different underlying PDF container type
- A value whose vertical position on the page is out of sequence with the values around it
- A starting balance, transaction list, and ending balance that don't reconcile
- The name of a known PDF editing tool embedded in the file, or an edit flag left behind by software
None of these checks need an outside reference. A statement generated once by one banking system wouldn't contain these contradictions in the first place.
Model two: inter-document consistency
The second model compares the document against consistencies drawn from a population of known-authentic PDFs, most usefully verified statements from the same issuing institution. MoneyThumb calls this the institution's fingerprint: the structural and formatting pattern that a bank's real statements follow.
This catches fraud the first model can't. A cloned template or a fully synthetic statement may be internally flawless because it was generated, never edited. It still won't match the fingerprint of the bank it claims to come from, and the inter-document model flags the operators and formatting patterns that are out of place for that source.
Weighting artifacts into one score
Each artifact carries a weight, and per the patent, that weight varies. An explicit edit flag can push a score high on its own. A single character sitting a fraction of a point off its column is minor by itself and matters when it recurs or appears alongside other artifacts.
A predictive model trained on libraries of known-authentic and known-altered documents evaluates both scores together and produces one alteration score. Any score above zero comes with its contributing factors, and in many cases the exact location in the document that triggered them.
| Score | Meaning |
|---|---|
| -1 | Image-based file (scan or photo); ThumbPrint does not score these today |
| 0 | No abnormalities found |
| 1 to 299 | Low risk |
| 300 to 700 | Moderate risk, worth a closer look |
| 701 to 999 | High risk, warrants close scrutiny |
| 1000 | Typically direct evidence of editing |
Why 2.2 million statements a month changes the math
The inter-document model is only as strong as the population it compares against. A fingerprint built from twenty statements from a regional credit union is weak. One built from thousands is reliable.
Every month, MoneyThumb sees roughly 2.2 million bank statements for the first time, and it has catalogued over 140,000 unique statement formats from institutions around the world. That number counts only new documents. Resubmissions and duplicates of the same statement are excluded, so each month adds millions of fresh, distinct examples to the baseline. The patent defines how to compare a document against authentic examples. That volume determines how many institutions have enough authentic examples to compare against.
This shows up in two places. The first is the long tail: credit unions, community banks, neobanks, fintech-issued accounts, and foreign institutions that are common when underwriting underbanked small businesses. Generic fraud models have the least data on these sources. MoneyThumb has processed the most.
The second is adaptation speed. When a bank updates its statement template or a new issuer appears, early documents in that format can score higher because the model hasn't seen enough genuine examples yet. A careful human reviewer would treat an unfamiliar layout the same way. With roughly 2.2 million never-before-seen statements arriving each month, new formats collect authentic examples quickly and their scores settle fast. A competitor can copy a feature list. Years of format history are much harder to replicate.
A case a metadata check would miss
Someone takes a real statement, changes the ending balance, and scrubs the metadata. A metadata-only tool finds no edit flag and reports the file clean.
ThumbPrint's intra-document model may catch that the PDF objects around the edited field are structured differently from the rest of the page. The inter-document model may find that the font or formatting at that spot doesn't match the bank's fingerprint. Either signal alone may be inconclusive. Together, they raise the alteration score and send the file to review.
The fallback when open banking can't connect
Open banking is the cleanest data source when it works, and in SMB lending it often doesn't. Merchants decline to share credentials. Smaller institutions aren't supported by aggregators. Connections break mid-application. Many international banks have no supported connection at all.
When that happens, underwriting falls back to the PDF statement, which is exactly the artifact a fraudster can edit. ThumbPrint makes that fallback trustworthy. Every statement arriving through a broker portal, email, or direct upload gets scored and explained, so lenders can keep funding merchants who can't or won't connect without underwriting blind.
Why the patent matters for developers and product teams
If you build an LOS, a broker submission portal, or a decisioning engine, the value of the patent shows up in how its output behaves inside your system.
Results are deterministic and explainable. The same document returns the same score and the same contributing factors every time. That makes results reproducible in QA, testable in staging, and defensible when compliance or an applicant asks why a file was held. We cover why this matters across the whole underwriting pipeline in Deterministic Document Parsing vs. Probabilistic AI.
Scores map cleanly to routing rules. The bands give you natural thresholds. A common pattern is to pass 0 straight through, queue the moderate band for review, hold anything above 700, and treat 1000 as confirmed editing. Build a separate path for -1, such as requesting a native PDF from the merchant, so image files are never mistaken for clean ones.
Reasons can go straight into your UI. Contributing factors, and often the location of the artifact, can be shown directly to an underwriter, who can go to the flagged balance and make a call in seconds.
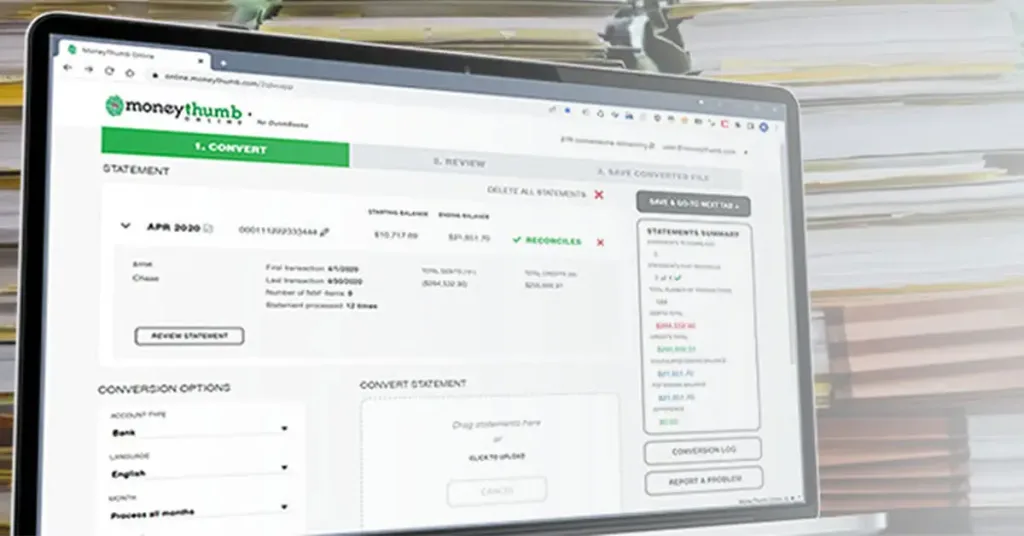
There's no extra integration step. ThumbPrint runs on every document processed through PDF Insights, so the fraud score arrives alongside the parsed statement data.
The signal holds up over time. Because the analysis goes well beyond metadata, your fraud logic won't quietly degrade as fraudsters get better at scrubbing files.
The takeaway
Document fraud in higher-risk SMB lending is rising, and open banking won't cover every applicant. ThumbPrint pairs a patented two-model method with the largest statement dataset in the space, so every PDF in your workflow gets a score you can explain, audit, and build on.



Add comment